
Most businesses already have the information they need to automate more work. The problem is where that information lives.
A supplier sends an invoice as a PDF attachment. Procurement receives a revised purchase order by email. Operations tracks exceptions in a spreadsheet. Finance copies approved values into an ERP. A manager checks the final numbers before payment.
People can follow that process because they understand context. They know which attachment matters, which spreadsheet column is authoritative and when an unusual amount deserves a second look.
AI can automate part of that work, but reliable automation takes more than extracting text from a document. The system has to understand what arrived, identify the information that matters, validate it against trusted business data, handle uncertainty and know when a person should review the result before anything changes downstream.
That is the difference between impressive document extraction and useful AI process automation.
The hardest part is not reading the document
Consider a finance team that receives several hundred supplier invoices each week.
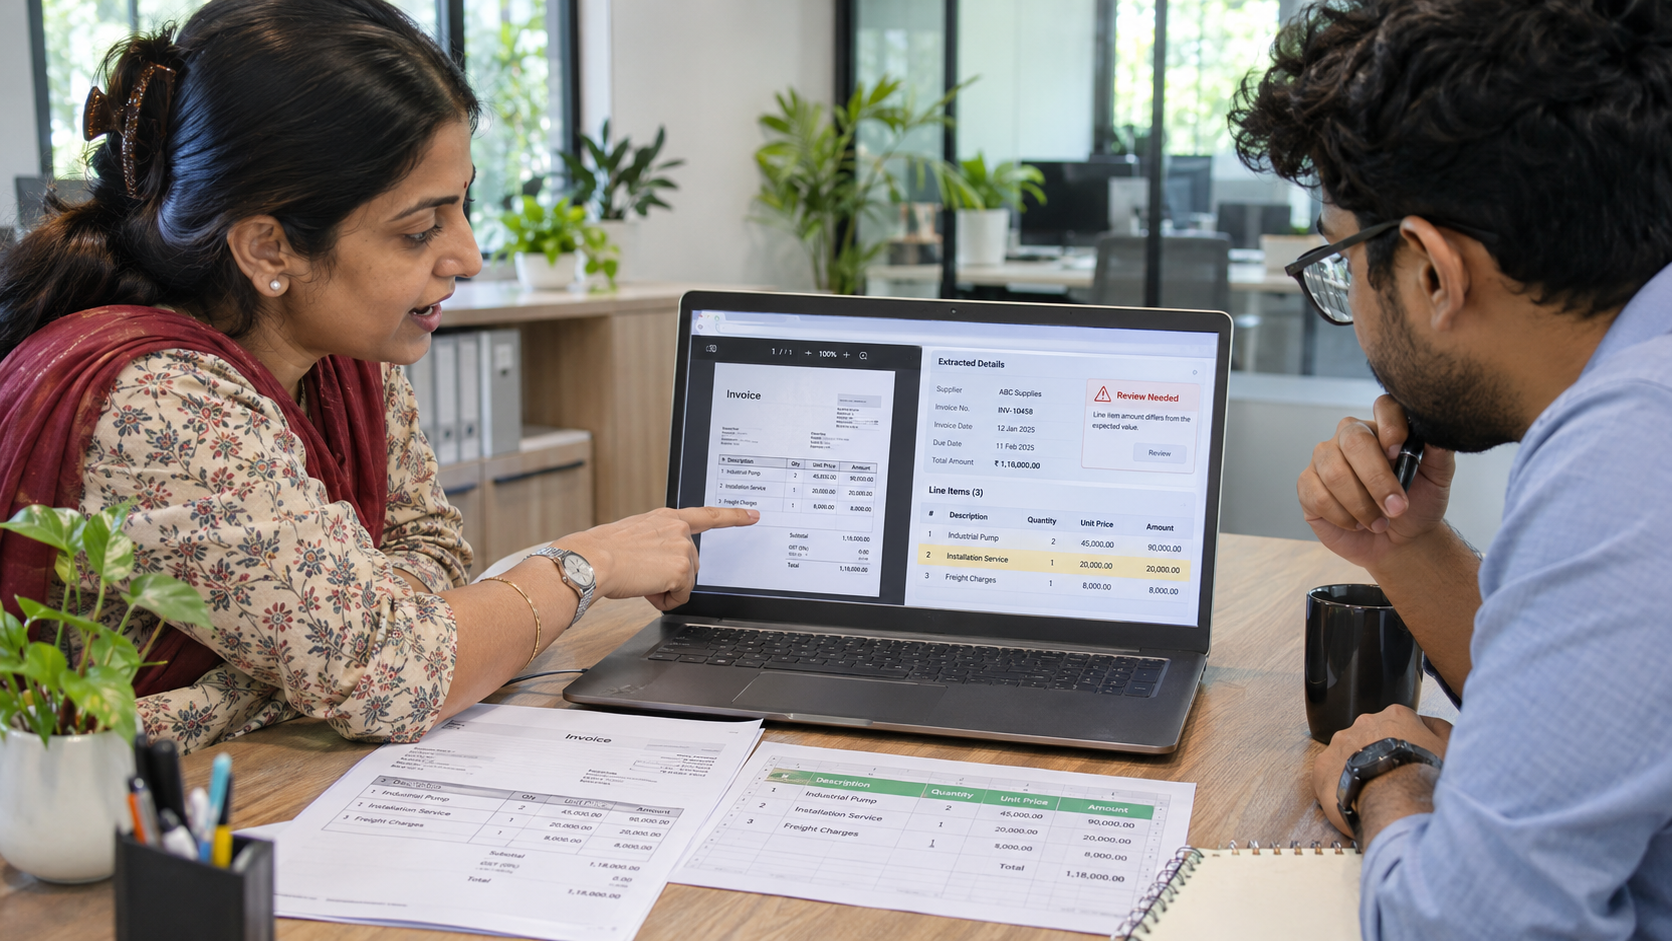
Today, an employee opens the email, downloads the attachment, checks the supplier, finds the purchase-order number, compares the amount with the approved PO and then enters the information into the finance system.
On paper, this looks like a perfect automation candidate.
An AI system can certainly read many of those documents. Modern document-processing platforms can extract text, tables, key-value pairs and structured fields from PDFs, scans and forms. Microsoft and AWS both provide confidence information that can help teams decide whether an extracted result can continue automatically or needs additional review.
But reading the invoice is only one step.
Suppose the system correctly extracts:
- supplier name;
- invoice number;
- purchase-order reference;
- invoice total.
It still needs to know whether the supplier exists, whether the PO is valid, whether the invoice has already been processed and whether the amount matches what the business approved.
A perfectly extracted value can still produce the wrong business action.
That is why reliable document automation needs to be designed around the whole workflow, not around the model alone.
Emails, PDFs and spreadsheets create different kinds of uncertainty
Business information is often described as either structured or unstructured, but real workflows usually contain a mixture of both.
A well-maintained spreadsheet may have predictable columns and data types. An invoice PDF is semi-structured: the same information appears repeatedly, but every supplier may place it somewhere different. Contracts and long email threads are more difficult because the meaning can depend on paragraphs, context and wording rather than a fixed field.
Microsoft's document-processing guidance reflects this difference. Structured and semi-structured documents can often use deterministic or specialised extraction approaches, while more varied unstructured content may require models that interpret context.
For a business, that means one automation technique should not be forced onto every source.
A stable spreadsheet import might need validation rules rather than generative AI. A predictable invoice template may be handled effectively with document extraction. A contract containing several differently worded termination clauses may require a more contextual approach, followed by human review. Microsoft’s guidance on choosing the appropriate document-processing approach similarly distinguishes between structured forms, unstructured documents and use cases that need confidence scoring or contextual interpretation.
The right question is not simply, “Can AI read this?”
It is:
How much interpretation is required before this information becomes safe enough to trigger the next business action?
Follow the invoice all the way to the ERP
Take the supplier invoice example again.
The invoice arrives by email. Before anything reaches the ERP, several decisions have to happen.
The system first needs to recognise that the attachment is an invoice rather than a quote, credit note or unrelated document. It needs to extract the relevant fields and associate them with the correct supplier and purchase order.
Then the business rules begin.
Perhaps the PO exists, but the invoice amount is 18% higher than the approved value. Maybe the supplier name is correct but the bank details have changed. The document could even be a duplicate invoice with a different filename.
At this point, asking the AI to “decide” everything is usually unnecessary.
AI can interpret the messy input. Existing databases, APIs and business rules can verify what should be true.
That combination is often much more dependable.
A useful workflow might therefore look like:
email received → document identified → fields extracted → supplier and PO validated → exception checked → human review where necessary → ERP record created → outcome logged
The reliability comes from the chain.
A Document Automation Decision Matrix helps define how much AI is appropriate
Different workflows deserve different levels of autonomy. A low-risk categorisation task and a high-value financial transaction should not use the same threshold simply because both involve PDFs.
A practical decision matrix can help:
| Situation | Sensible automation approach |
|---|---|
| Fixed document format with predictable fields | Deterministic extraction plus validation |
| Several known document layouts | Document AI or trained extraction |
| Highly variable documents requiring contextual interpretation | Generative extraction with grounding and validation |
| Important field has low extraction confidence | Route the field or document for human review |
| Extracted value conflicts with ERP/CRM data | Stop automatic action and create an exception |
| Financial, contractual or other high-impact decision | Keep approval with an authorised person where appropriate |
| No reliable source exists to validate the result | Avoid full straight-through automation |
| Documents and business rules change constantly | Stabilise the process before increasing automation |
The important factor is not just document complexity.
It is the cost of being wrong.
AWS's document-processing guidance explicitly recommends using confidence thresholds according to the sensitivity of the use case. It notes that workflows involving financial decisions may need substantially higher confidence and greater human scrutiny than lower-risk uses.
That is a more useful way to think about automation than chasing one universal accuracy number.
Confidence should affect the next action, not produce one pass/fail score
Suppose the system extracts these values:
| Field | Example confidence |
|---|---|
| Supplier | 99% |
| Invoice number | 98% |
| PO reference | 94% |
| Total amount | 66% |
It would be a mistake to average those numbers and decide that the document is “good enough.”
The total amount may be the field that matters most.
A better workflow can accept the high-confidence fields, verify them against business systems and send only the uncertain amount for review. Microsoft’s documentation on confidence scores and human-review routing recommends using confidence values to automate higher-confidence results while routing lower-confidence fields for manual verification, with grounding used to trace extracted values back to their source
That makes human review faster because the person is not repeating the entire extraction process. They are checking the part the system could not resolve confidently.
Validation is usually more important than another AI model
One of the easiest mistakes in document automation is to keep adding AI where ordinary business logic would be more reliable.
The model extracts an invoice number.
You do not need another model to decide whether the invoice has already been processed. Query the finance system.
The model identifies a purchase-order number.
You do not need AI to guess whether the PO is valid. Check the ERP.
The system reads an amount.
A rules engine can compare that amount against approval limits, expected totals or purchase-order values.
This is where well-designed AI automation services become broader than model selection. The engineering work lies in connecting AI to the systems that know whether the extracted information makes business sense.
For teams exploring automating document-heavy business workflows with AI, the architecture between the document and the final action is usually more important than the extraction demo itself.
Human review should solve an exception, not repeat the entire job
A human-in-the-loop workflow is sometimes described as a compromise: automation works until it fails, and then somebody handles everything manually.
That is poor workflow design.
The reviewer should know exactly why the case reached them.
Imagine three invoices.
The first matches its PO and all critical fields are high confidence. It may be suitable for straight-through processing.
The second was read correctly, but the value exceeds the approved purchase order. That is a business-rule exception.
The third contains an amount that the model cannot confidently distinguish from another value on the page. That is an extraction exception.
The reviewer needs different information in each case.
For the second invoice, they need the invoice, PO and variance. For the third, they need the original page and highlighted source field.
Good automation reduces the amount of reasoning a person has to repeat.
NIST's AI Risk Management Framework also emphasises ongoing testing, monitoring, governance and human intervention where AI systems cannot adequately identify or correct errors.
Human review is therefore not a sign that the system failed. Sometimes it is the control that makes automation safe enough to use. This also aligns with the NIST AI Risk Management Framework, which treats AI risk management as an ongoing process covering design, deployment, monitoring and governance rather than a one-time model-accuracy check.
Spreadsheets may be structured, but that does not make the data clean
A spreadsheet often looks easier than a PDF because the information already sits in rows and columns.
Then someone opens the file.
Dates appear in three formats. Required cells are blank. Product names are entered differently by different teams. A formula was replaced with a hard-coded number two months ago. There are five tabs, and nobody is completely sure which one should be treated as current.
AI can help interpret inconsistent text or classify records, but it cannot automatically turn weak data governance into trustworthy automation.
Before connecting a spreadsheet to another system, the team should know which fields are authoritative, what validation rules apply and what happens when a value conflicts with the ERP or CRM.
Sometimes the right automation decision is not to build a smarter spreadsheet reader.
It is to remove the spreadsheet from that part of the process.
Email workflows are difficult because meaning can be split across the message and attachment
A purchase-order PDF may say one thing while the email containing it adds an important qualification.
For example: Please use the revised quantities in the attached PO. The delivery date remains unchanged from our previous order.
If the workflow processes only the attachment, it may miss the instruction.
If it reads only the email, it does not have the line-item information needed for the ERP.
A useful system therefore needs to treat the email and attachment as parts of the same business event.
It may classify the message intent, associate the correct attachment, extract the document values, compare them with existing records and then determine whether the requested change is within an approved workflow.
That is AI process automation rather than simple email classification.
The objective is not to label the message accurately.
It is to move the business process forward without losing the context that made the message meaningful.
Reliability should be measured after the workflow runs, not only after extraction
Model accuracy matters, but it does not tell management whether the automation is working.
Suppose an invoice extractor achieves excellent field accuracy but supplier matching frequently links invoices to the wrong vendor account. Operationally, the workflow is still unreliable.
The useful measures are closer to the final business outcome.
Teams might track the percentage of documents requiring correction, the number routed to human review, downstream system rejection rates, duplicate transactions, exception-resolution time and cases that had to be completely reprocessed manually.
Those numbers reveal where the automation is actually creating work.
A model improvement that raises extraction accuracy slightly may matter less than fixing a validation problem that eliminates dozens of downstream exceptions.
Test the documents your team hates
A polished proof of concept usually uses the cleanest samples available.
Production does not.
Before approving a document workflow, test an invoice with a poor scan. Use a supplier layout the model has not seen. Upload a spreadsheet with missing cells and inconsistent dates. Send an email where the message contradicts one detail in the attachment.
Then follow the result all the way to the end.
Did the system identify the document correctly? Did it extract the important fields? Could a reviewer see where the extracted values came from? Did validation catch the discrepancy? Did the exception reach the right person? Did the ERP receive the correct result only after the problem was resolved?
That is a far better test of operational reliability than asking whether the AI can process a perfect invoice in a demo.
What should you ask an automation company before giving AI permission to act?
Once a workflow moves beyond extraction and starts changing business systems, vendor evaluation should become more specific.
When evaluating an automation company, ask what happens when the AI is uncertain. Ask how extracted fields are validated against existing systems, how thresholds are set, which actions still require approval and whether the team can trace why a particular record was created or changed.
Also ask how the workflow behaves when the source changes.
What happens if a supplier redesigns its invoice next month? If an email contains two attachments? If the ERP is unavailable? If a user corrects a value after extraction?
The answer should not simply be “the AI learns.”
Reliable automation needs explicit exception paths.
Aquarious Technology's current AI Automation service describes workflow automation integrated with CRM, ERP, email, databases and business tools, while retaining human oversight where appropriate.
That is the right level at which to evaluate a document-heavy automation project: not as an isolated AI model, but as part of the operational system around it.
Start with one workflow and define the automation boundary
A business does not need to automate every document to make meaningful progress.
Choose one repetitive process where employees already spend time moving information from documents into another system.
Map what arrives, what has to be extracted, which source can validate each important value, what can happen automatically and which exceptions need a person.
Then decide the automation boundary.
Perhaps the first version automatically classifies invoices, extracts the values and creates a draft ERP entry, but Finance still approves payment.
That can still remove substantial manual work.
Later, if the organisation has enough evidence that validation and exception controls are reliable, more of the workflow may be automated.
The goal is not maximum autonomy on day one.
It is a workflow that people can trust enough to use.
Frequently Asked Questions
Yes, particularly when document types and required fields are well understood. Reliability varies with document quality, layout variation and the complexity of the information being extracted. Critical values should be validated, and lower-confidence results may need human review.
Yes. A workflow can interpret the email, identify the relevant attachment, extract document data and combine both sources before taking action. This is particularly useful when instructions in the email modify or qualify information contained in the attachment.
No. OCR converts visible text into machine-readable text. Document automation can also classify files, identify fields, validate information against business systems, route exceptions and trigger downstream actions.
Not necessarily. The threshold should depend on the field and the consequence of an incorrect result. A low-risk categorisation may tolerate more uncertainty than an invoice value, contractual term or other high-impact field.
Full autonomy is usually a poor choice when source documents are highly inconsistent, business rules are unclear, no reliable validation source exists, exceptions dominate the process or an incorrect action would create significant financial, legal or operational consequences.