
A useful AI feature often feels almost invisible to the person using it.
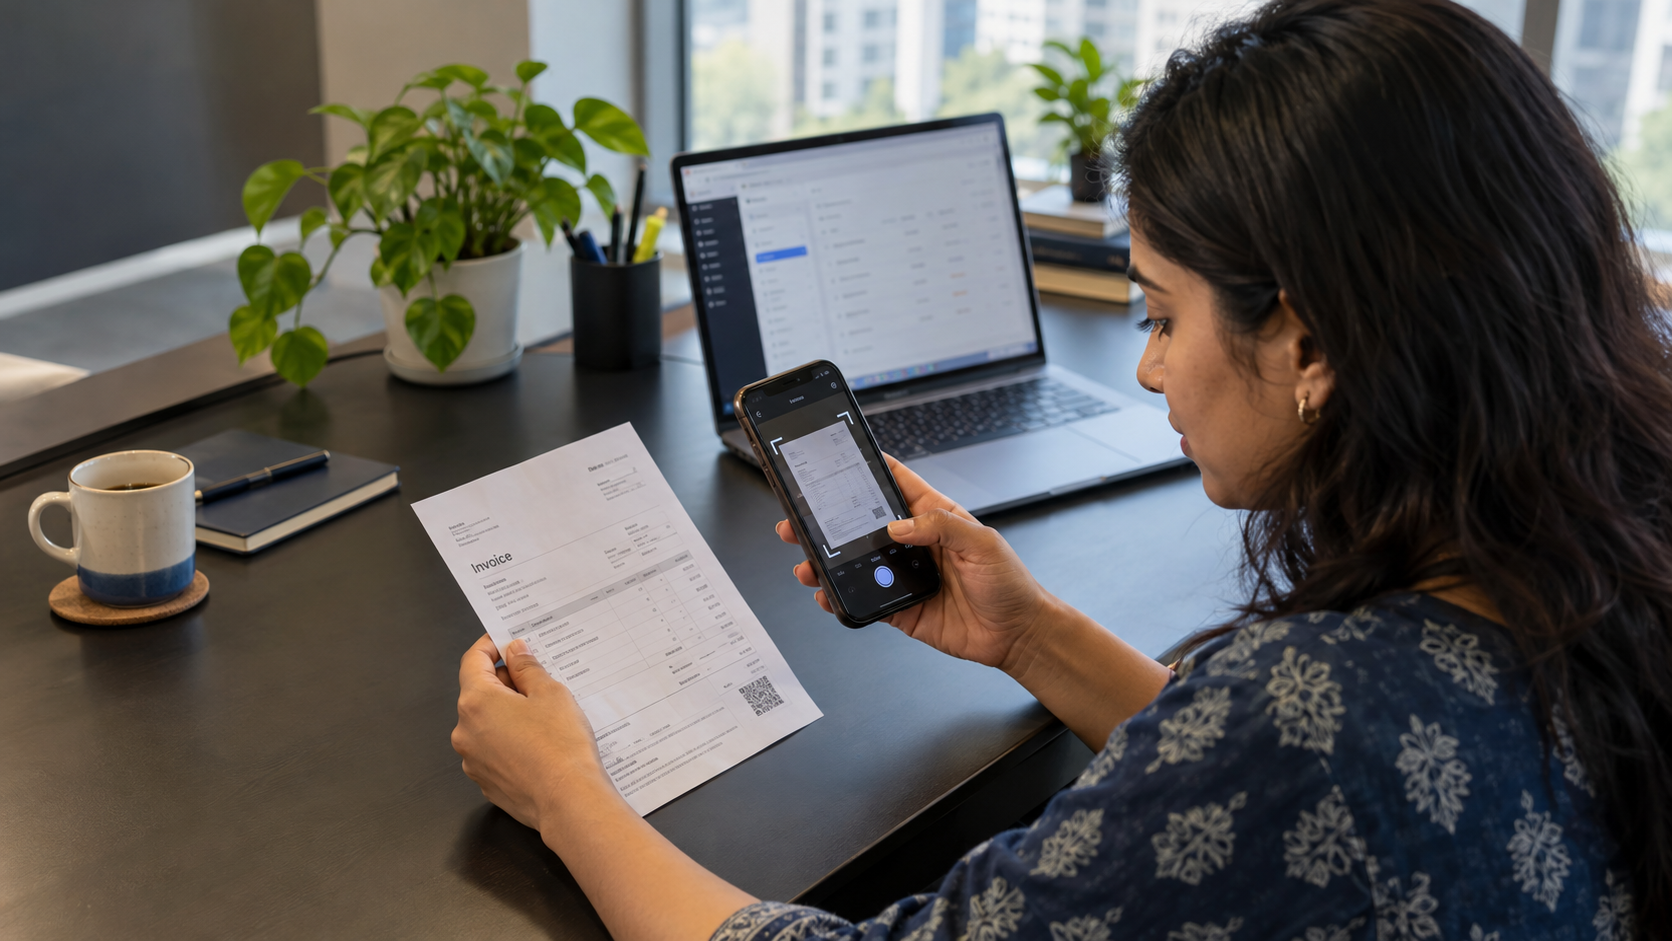
Someone points a phone at a document and the text appears. A field employee speaks an update and the app turns it into a structured note. A customer asks for help and gets a relevant answer without digging through several screens.
What the user does not see is the architecture behind that response.
Some AI work can happen directly on the phone. Other tasks make more sense in the cloud, where the application can use larger models, business data and more computing power. In many products, the sensible answer is not one or the other. It is a combination.
The decision matters because it affects much more than the model itself. It changes how quickly the feature responds, what happens without internet access, how much data leaves the device, which phones can support the experience and what the product may cost to operate as usage grows.
Choosing the architecture early saves a lot of uncomfortable redesign later.
On-device AI works well when immediacy matters
On-device AI processes the task locally on the phone or tablet.
For a bounded task, this can make the experience feel remarkably natural. The app does not have to send every input to a remote service and wait for a response.
Google's ML Kit is a good example. Its supported features run on-device, which makes real-time and offline use possible for tasks such as text recognition, barcode scanning and language-related processing.
That matters in situations where connectivity cannot be taken for granted.
Imagine an employee scanning labels inside a warehouse. If recognition depends on uploading every image to a remote service, weak coverage becomes part of the workflow. Local processing removes that dependency for the recognition step.
The same approach can be useful in field-service applications, travel tools and mobile workflows where users regularly move between strong and weak networks.
There is also a privacy advantage in some cases. If a photo, note or other input can be processed locally, that information may not need to leave the device for the AI task to work.
This does not make the whole app private by default. The application may still synchronise data or call other services. It simply reduces unnecessary data movement for the part that can remain local.
Google’s ML Kit on-device processing supports mobile machine-learning tasks such as text recognition, barcode scanning and language-related processing without requiring every input to be sent to a remote server.
The phone still has limits
The attraction of on-device AI can make teams forget one practical detail: the user's phone has to do the work.
Phones differ.
A model that runs comfortably on a recent flagship device may behave very differently on an older handset with less memory and slower processing.
The model itself also has to fit somewhere. Larger models can take storage, memory and download time. More demanding inference can affect battery life and, under sustained load, device temperature.
This becomes particularly important on Android, where device diversity is substantial.
A development team can easily test a new AI feature on powerful internal devices and conclude that performance is fine. The real test is the hardware your users actually carry.
For business applications, that point is easy to underestimate. If a company has a mixed device fleet, designing only for the newest phones can turn an impressive feature into a support problem.
Cloud AI solves a different class of problem
Cloud AI removes many of those device constraints.
The mobile application sends a request to a remote service, the model processes it, and the result comes back to the app.
That makes larger models much easier to use.
Consider a support assistant inside a customer app. It may need access to order history, account data, product documentation and backend tools. Trying to package all of that intelligence into the phone would usually make little sense.
The cloud is a more natural place for those tasks because it already has access to the systems and computing power involved.
It also gives the product team more control over updates. Models, prompts and routing logic can often be changed centrally without waiting for every user to install a new app release.
The trade-off is that the experience now depends on the network and a remote service.
A weak connection can become visible to the user. Every request may create an infrastructure or API cost. Sensitive data may need to travel beyond the device, which changes the security and privacy design.
So cloud AI is not simply “more powerful AI.” It moves the constraints somewhere else.
Latency is not as simple as local versus remote
It is tempting to think that local AI is fast and cloud AI is slow.
Sometimes that is true. Not always.
A small model can respond very quickly on-device because there is no network round trip. A large model running on limited hardware may still feel sluggish.
A cloud system may process a complex request very quickly on server-grade hardware, but the user still has to wait for the request to travel out and the answer to come back.
The important factor is the interaction itself.
Camera-based recognition is a good example. A delay that might be acceptable for a generated report can feel irritating when the user expects the camera to react immediately.
The architecture should therefore be tied to the way the feature is used, not just to the raw speed of the model.
Offline requirements can settle the decision very quickly
For some applications, offline AI is a convenience.
For others, it is essential.
Field technicians, delivery teams and employees working inside industrial environments may not have stable connectivity throughout the day. If the AI feature disappears every time the network drops, the product may become unreliable at exactly the point when it is needed.
Local processing can keep a core function available.
An inspection app, for instance, might classify an image or read text locally and save the result on the device. Once the connection returns, the app can synchronise the record and send more demanding analysis to the cloud.
This kind of split is often more practical than insisting that the entire feature must be local or remote.
In many mobile products, hybrid AI is the sensible middle ground
A hybrid architecture divides the work.
The phone handles tasks where speed, privacy or offline operation matters. The cloud takes over when the feature needs a larger model, current business data or more computing power.
Google now documents this pattern directly through Firebase AI Logic, including hybrid inference where an application can use local capability when available and fall back to the cloud under other conditions.
The important idea is not the specific framework. It is the routing logic.
One feature can use more than one execution path.
A note-taking application could handle lightweight rewriting locally while sending a large research request to the cloud.
A retail app could recognise a product through the camera on-device and use cloud services to combine that result with inventory and customer history.
A field-service app might identify an asset locally, then ask a server-side model to analyse years of maintenance records before producing a recommendation.
The strongest mobile architecture is often the one that stops treating “AI” as a single workload.
Google now documents this pattern directly through Firebase AI Logic hybrid inference, where supported applications can combine on-device and cloud-based model execution rather than relying on a single inference path.
On-Device vs Cloud AI Decision Matrix
| Decision factor | On-device AI | Cloud AI | Hybrid approach |
|---|---|---|---|
| Privacy | Data can remain local for the AI task | Data may need secure transmission | Keep sensitive work local where possible |
| Latency | Strong for real-time, bounded tasks | Network time becomes part of response | Route according to interaction |
| Offline use | Can continue without connectivity | Usually network-dependent | Preserve selected functions locally |
| Model capability | Limited by device resources | Larger models are practical | Use each where it fits |
| Device support | Varies by hardware | More consistent across client devices | Cloud fallback can expand coverage |
| Operating cost | Less cloud inference usage | Cost grows with requests | Reduce unnecessary remote calls |
| Model updates | Distribution needs planning | Easier to update centrally | Combine stable local models with flexible cloud models |
| Battery and heat | Heavy processing can affect the device | Intensive compute stays remote | Shift demanding work to cloud |
| Backend access | Usually requires additional services | Natural fit for server-side systems | Keep UX local, business actions controlled on server |
A useful starting rule is simple:
Keep AI on the device when the task is relatively contained, needs immediate response, must work offline or benefits significantly from keeping data local. Use the cloud when the feature needs larger models, live backend information or server-side tools. Use both when the product genuinely has both kinds of work.
The final decision still needs testing on real devices and real network conditions.
Cost also changes depending on where the model runs
Cloud inference usually creates a visible usage cost.
As more users make more requests, API or infrastructure bills rise with them. For a feature used occasionally inside a high-value enterprise workflow, this may be perfectly reasonable.
A free consumer feature being called dozens of times per user per day is a different financial model.
On-device AI shifts some of that burden away from per-request infrastructure, but it does not make the feature free.
Engineering teams may spend more time optimising models, managing downloads, testing different devices and handling situations where local capability is unavailable.
The right architecture therefore depends partly on usage.
A product team should know roughly how often the feature will be used, by how many people and on what class of device before assuming one approach is cheaper.
Security needs to be designed around the boundary
Cloud-based AI adds another connection between the mobile application and a valuable remote service.
That connection needs protection.
Sensitive credentials should not simply be embedded in the mobile client. A downloaded application is distributed software, so teams should assume that its packaged resources can be inspected.
Authentication, authorization, rate limits and abuse controls normally belong on the server side.
The rest of the application still needs sound mobile security as well: secure storage, appropriate permissions, protected network traffic and clear handling of user data.
The OWASP Mobile Application Security project is a useful reference because it provides a dedicated mobile security standard and testing guidance rather than treating the mobile client like a conventional web front end.
AI does not replace those responsibilities. It adds another system boundary to them.
Model updates can become a product issue, not just an engineering issue
Cloud models are easier to change centrally, but that flexibility creates its own discipline.
A new model or revised prompt can change how the feature behaves without a normal app-store release.
That means the product team needs some way to test changes before exposing them broadly.
Local models create a different versioning challenge.
One group of users may have a device capable of running a newer model while another group does not. Some users may already have downloaded the model; others may not.
The application needs sensible fallback behaviour so the experience does not feel broken or random.
This becomes even more important for products that support both iOS and Android because the platforms do not always introduce equivalent AI capabilities at the same time.
Architecture should be decided before the feature is designed around the wrong assumptions
Where the AI runs affects more than the AI code.
It can change API design, supported devices, offline behaviour, infrastructure, privacy requirements, testing scope and operating cost.
That is why this decision belongs early in mobile product planning.
For businesses planning mobile application development in Kolkata, or working with development teams elsewhere, AI should be treated as an architectural requirement rather than a feature that can simply be plugged in near the end of the build.
An MVP also benefits from restraint. If the AI function is not central to the first user journey, it may be wiser to prove the product before adding another layer of technical complexity. Aquarious has covered this in its guide to keeping the first mobile release focused on the core user problem, where the emphasis is on validating the main experience before widening the scope.
What should you expect from a mobile development partner?
Being able to call an AI API is not the same as making a sound architecture decision.
A capable mobile team should be able to explain why a particular workload belongs on the device, in the cloud or across both.
Businesses comparing mobile app development agencies should expect the proposal to address device coverage, connectivity, privacy, cloud cost, security boundaries and fallback behaviour.
The same applies when evaluating a mobile app development company in Kolkata for an AI-enabled product. The technical recommendation should reflect the people using the application and the conditions in which they will use it, rather than a preference for a particular framework or model.
The Aquarious Technology approaches developing an AI-enabled mobile application within the wider mobile-development lifecycle, covering product discovery, architecture, Android/iOS or cross-platform development, integrations, testing, deployment and post-launch support.
The AI architecture is part of that lifecycle.
It should not be decided in isolation.
Frequently Asked Questions
Neither architecture is universally better. On-device AI is usually a better fit when the feature needs very low latency, offline operation or local processing of sensitive data. Cloud AI makes more sense when the application needs larger models, business data or server-side tools. Many products benefit from using both.
Yes. A hybrid architecture can use local models for appropriate tasks and route more demanding work to cloud models. It can also provide fallback behaviour when a device does not support local inference or when connectivity changes.
Yes, if the necessary model and resources are available on the device. On-device tools such as Google ML Kit support several offline processing use cases. Features that rely on cloud-hosted models or current server-side information will still require connectivity.
No. Local processing can reduce the amount of data sent to remote services, but the overall privacy of the app still depends on storage, permissions, APIs, analytics and the wider data flow.
The feature should be assessed against device support, offline requirements, data sensitivity, response-time expectations, model capability, backend access and likely usage cost. Those factors usually reveal whether local, cloud or hybrid inference is the better fit.
The User Should Not Have to Care Where the AI Runs
A well-designed mobile feature does not advertise its architecture.
The user simply notices that it works.
The camera responds quickly. The assistant has enough context. The app still performs the important parts of its job when connectivity is weak. Sensitive information is not moved around without a reason.
Achieving that may require one model on the device and another in the cloud. It may also require the application to change routes quietly depending on hardware or network conditions.
That complexity belongs behind the product.
The architecture discussion becomes easier once the team stops asking where *all* of the AI should run and starts looking at each task individually.